beautifulsoup4 4.12.2
Beautiful Soup is a library that makes it easy to scrape information from web pages. It sits atop an HTML or XML parser, providing Pythonic idioms for iterating, searching, and modifying the parse tree.
Quick start
>>> from bs4 import BeautifulSoup >>> soup = BeautifulSoup("SomebadHTML") >>> print(soup.prettify())
Some bad HTML
>>> soup.find(text="bad") 'bad' >>> soup.i HTML # >>> soup = BeautifulSoup("SomebadXML", "xml") # >>> print(soup.prettify()) Some bad XML Links
- Homepage
- Documentation
- Discussion group
- Development
- Bug tracker
- Complete changelog
Note on Python 2 sunsetting
Beautiful Soup’s support for Python 2 was discontinued on December 31, 2020: one year after the sunset date for Python 2 itself. From this point onward, new Beautiful Soup development will exclusively target Python 3. The final release of Beautiful Soup 4 to support Python 2 was 4.9.3.
Supporting the project
If you use Beautiful Soup as part of your professional work, please consider a Tidelift subscription. This will support many of the free software projects your organization depends on, not just Beautiful Soup.
If you use Beautiful Soup for personal projects, the best way to say thank you is to read Tool Safety, a zine I wrote about what Beautiful Soup has taught me about software development.
Building the documentation
The bs4/doc/ directory contains full documentation in Sphinx format. Run make html in that directory to create HTML documentation.
Running the unit tests
Beautiful Soup supports unit test discovery using Pytest:
$ pytest Установка Beautifulsoup и примеры
Разберем как производится установка beautifulsoup — библиотеки, которая позволяет работать с содержимым веб-страниц в интернете, извлекая из больших объемов структурированной информации нужную. Используется для парсинга.
Python beautifulsoup: установка и использование, примеры
Прежде всего, создадим виртуальное окружение. Назвать его можно, например, parser
Подробнее о виртуальном окружении и необходимых для его работы пакетах
(parser) admin@desktop:/
В терминале после активации появляется указанное ранее имя.
Как установить beautifulsoup python
BeautifulSoup является частью библиотеки bs4, парсер также требует requests, все устанавливается через pip из окружения
Successfully installed certifi-2018.8.24 chardet-3.0.4 idna-2.7 requests-2.19.1 urllib3-1.23 beautifulsoup4-4.6.3 bs4-0.0.1
Пример вывода на скриншоте:
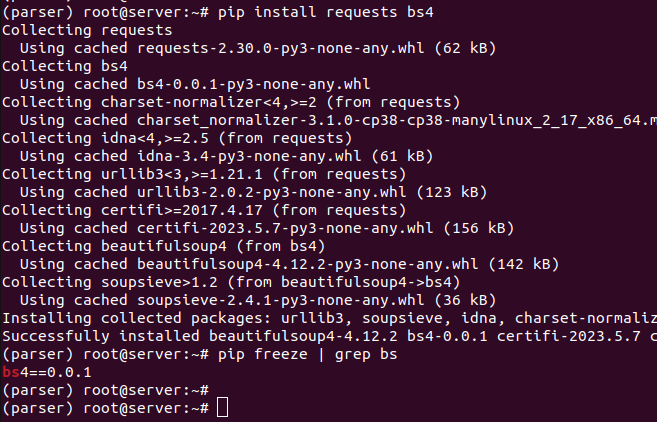
Установка завершена, теперь можно перейти к созданию скрипта
import requests from bs4 import BeautifulSoup page = requests.get('https://yandex.ru') soup = BeautifulSoup(page.text, 'html.parser')
Создается объект BeautifulSoup, в скобках указываются два параметра.
Первый — результат применения метода text к содержимому переменной page. Переменная page содержит текст страницы, путь к которой задан.
Второй аргумент — html.parser
С данными далее можно производить любые манипуляции.
Пример форматирования результата полученного с помощью BeautifulSoup
Добавим в скрипт такие строки
city = soup.find(class_='geolink__reg') print (city.prettify())
Вызов скрипта из консоли
Скрипт спарсил главную страницу Яндекса и получил содержимое тега с классом geolink__reg из HTML кода. Класс выбран для демонстрации при визуальном анализе исходного кода (CTRL+U в браузере).
В данном случае в нем находится город, определенный при помощи geoip
Здесь используется метод prettify, который позволяет создавать отформатированное дерево тегов с результатами поиска.
Теперь закомментируем последний print и вместо него
city = soup.find(class_='geolink__reg') #print (city.prettify) print (city.contents[0])
Если вызвать скрипт сейчас можно увидеть, что он отдает только сам контент, в данном случае — имя города.
Екатеринбург
Это достигнуто использованием contents[0], все лишние тэги удалены. Результаты парсинга можно сохранять в csv файлы или обычные текстовые документы. Записывать можно не все, а выбирать только нужное содержимое работая с ним как с текстом.
Скрипты с BeautifulSoup можно запускать по какому-то расписанию по системному планировщику задач CRON
Beautiful Soup — Installation
As BeautifulSoup is not a standard python library, we need to install it first. We are going to install the BeautifulSoup 4 library (also known as BS4), which is the latest one.
To isolate our working environment so as not to disturb the existing setup, let us first create a virtual environment.
Creating a virtual environment (optional)
A virtual environment allows us to create an isolated working copy of python for a specific project without affecting the outside setup.
Best way to install any python package machine is using pip, however, if pip is not installed already (you can check it using – “pip –version” in your command or shell prompt), you can install by giving below command −
Linux environment
$sudo apt-get install python-pip
Windows environment
To install pip in windows, do the following −
- Download the get-pip.py from https://bootstrap.pypa.io/get-pip.py or from the github to your computer.
- Open the command prompt and navigate to the folder containing get-pip.py file.
- Run the following command −
>python get-pip.py
That’s it, pip is now installed in your windows machine.
You can verify your pip installed by running below command −
>pip --version pip 19.2.3 from c:\users\yadur\appdata\local\programs\python\python37\lib\site-packages\pip (python 3.7)
Installing virtual environment
Run the below command in your command prompt −
>pip install virtualenv
After running, you will see the below screenshot −
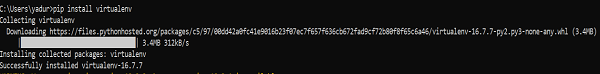
Below command will create a virtual environment (“myEnv”) in your current directory −
>virtualenv myEnv
Screenshot
To activate your virtual environment, run the following command −
>myEnv\Scripts\activate
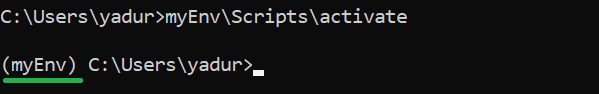
In the above screenshot, you can see we have “myEnv” as prefix which tells us that we are under virtual environment “myEnv”.
To come out of virtual environment, run deactivate.
(myEnv) C:\Users\yadur>deactivate C:\Users\yadur>
As our virtual environment is ready, now let us install beautifulsoup.
Installing BeautifulSoup
As BeautifulSoup is not a standard library, we need to install it. We are going to use the BeautifulSoup 4 package (known as bs4).
Linux Machine
To install bs4 on Debian or Ubuntu linux using system package manager, run the below command −
$sudo apt-get install python-bs4 (for python 2.x) $sudo apt-get install python3-bs4 (for python 3.x)
You can install bs4 using easy_install or pip (in case you find problem in installing using system packager).
$easy_install beautifulsoup4 $pip install beautifulsoup4
(You may need to use easy_install3 or pip3 respectively if you’re using python3)
Windows Machine
To install beautifulsoup4 in windows is very simple, especially if you have pip already installed.
>pip install beautifulsoup4
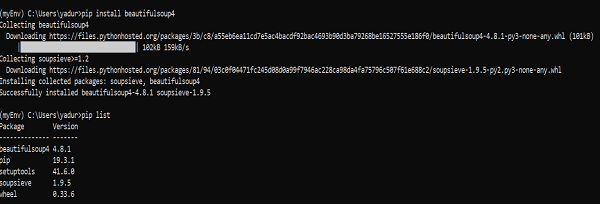
So now beautifulsoup4 is installed in our machine. Let us talk about some problems encountered after installation.
Problems after installation
On windows machine you might encounter, wrong version being installed error mainly through −
- error: ImportError “No module named HTMLParser”, then you must be running python 2 version of the code under Python 3.
- error: ImportError “No module named html.parser”error, then you must be running Python 3 version of the code under Python 2.
Best way to get out of above two situations is to re-install the BeautifulSoup again, completely removing existing installation.
If you get the SyntaxError “Invalid syntax” on the line ROOT_TAG_NAME = u’[document]’, then you need to convert the python 2 code to python 3, just by either installing the package −
$ python3 setup.py install
or by manually running python’s 2 to 3 conversion script on the bs4 directory −
$ 2to3-3.2 -w bs4
Installing a Parser
By default, Beautiful Soup supports the HTML parser included in Python’s standard library, however it also supports many external third party python parsers like lxml parser or html5lib parser.
To install lxml or html5lib parser, use the command −
Linux Machine
$apt-get install python-lxml $apt-get insall python-html5lib
Windows Machine
$pip install lxml $pip install html5lib
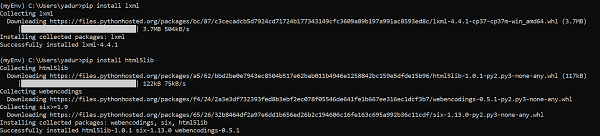
Generally, users use lxml for speed and it is recommended to use lxml or html5lib parser if you are using older version of python 2 (before 2.7.3 version) or python 3 (before 3.2.2) as python’s built-in HTML parser is not very good in handling older version.
Running Beautiful Soup
It is time to test our Beautiful Soup package in one of the html pages (taking web page – https://www.tutorialspoint.com/index.htm, you can choose any-other web page you want) and extract some information from it.
In the below code, we are trying to extract the title from the webpage −
from bs4 import BeautifulSoup import requests url = "https://www.tutorialspoint.com/index.htm" req = requests.get(url) soup = BeautifulSoup(req.text, "html.parser") print(soup.title)
Output
H2O, Colab, Theano, Flutter, KNime, Mean.js, Weka, Solidity, Org.Json, AWS QuickSight, JSON.Simple, Jackson Annotations, Passay, Boon, MuleSoft, Nagios, Matplotlib, Java NIO, PyTorch, SLF4J, Parallax Scrolling, Java Cryptography
One common task is to extract all the URLs within a webpage. For that we just need to add the below line of code −
for link in soup.find_all('a'): print(link.get('href'))
Output
https://www.tutorialspoint.com/index.htm https://www.tutorialspoint.com/about/about_careers.htm https://www.tutorialspoint.com/questions/index.php https://www.tutorialspoint.com/online_dev_tools.htm https://www.tutorialspoint.com/codingground.htm https://www.tutorialspoint.com/current_affairs.htm https://www.tutorialspoint.com/upsc_ias_exams.htm https://www.tutorialspoint.com/tutor_connect/index.php https://www.tutorialspoint.com/whiteboard.htm https://www.tutorialspoint.com/netmeeting.php https://www.tutorialspoint.com/index.htm https://www.tutorialspoint.com/tutorialslibrary.htm https://www.tutorialspoint.com/videotutorials/index.php https://store.tutorialspoint.com https://www.tutorialspoint.com/gate_exams_tutorials.htm https://www.tutorialspoint.com/html_online_training/index.asp https://www.tutorialspoint.com/css_online_training/index.asp https://www.tutorialspoint.com/3d_animation_online_training/index.asp https://www.tutorialspoint.com/swift_4_online_training/index.asp https://www.tutorialspoint.com/blockchain_online_training/index.asp https://www.tutorialspoint.com/reactjs_online_training/index.asp https://www.tutorix.com https://www.tutorialspoint.com/videotutorials/top-courses.php https://www.tutorialspoint.com/the_full_stack_web_development/index.asp …. …. https://www.tutorialspoint.com/online_dev_tools.htm https://www.tutorialspoint.com/free_web_graphics.htm https://www.tutorialspoint.com/online_file_conversion.htm https://www.tutorialspoint.com/netmeeting.php https://www.tutorialspoint.com/free_online_whiteboard.htm https://www.tutorialspoint.com https://www.facebook.com/tutorialspointindia https://plus.google.com/u/0/+tutorialspoint http://www.twitter.com/tutorialspoint http://www.linkedin.com/company/tutorialspoint https://www.youtube.com/channel/UCVLbzhxVTiTLiVKeGV7WEBg https://www.tutorialspoint.com/index.htm /about/about_privacy.htm#cookies /about/faq.htm /about/about_helping.htm /about/contact_us.htm
Similarly, we can extract useful information using beautifulsoup4.
Now let us understand more about “soup” in above example.
Kickstart Your Career
Get certified by completing the course
Туториал по библиотеке BeautifulSoup4
Парсеры — это программы, которые скачивают из интернета странички и разбирают их на составляющие: заголовок, картинка, текст… С помощью него можно выкачать с сайта гигабайты полезной информации. Библиотека BeautifulSoup4 как раз предназначена для парсинга.
В этой статье вы узнаете как распарсить сайт Франка Сонненберга. Цель: по ссылке на пост вытащить его название, текст и картинку.
Франк Сонненберг — известный американский писатель и коуч. За свои книги он попал в “Топ 100 Американских мыслителей”, а его блог принадлежит списку “Лучшие блоги о лидерстве 21 века”.
Прежде чем начинать…
Для прохождения этого туториала вам понадобятся 3 библиотеки:
$ pip install requests BeautifulSoup4 lxml Получить страничку поста
Будем парсить пост “Are You Grateful?”. Чтобы распарсить HTML-страничку с постом, сначала нужно её скачать. Это можно сделать с помощью requests , вот статья об этой библиотеке.
import requests url = 'https://www.franksonnenbergonline.com/blog/are-you-grateful/' response = requests.get(url) response.raise_for_status() print(response.text) Здесь мы просто сделали запрос по ссылке и получили в ответ огромный HTML. Начинаться он будет примерно так:
DOCTYPE html> html lang="en-US"> head > meta charset="UTF-8" /> meta name="viewport" content="width=device-width, initial-scale=1" /> . Парсинг поста
У вас есть HTML страничка, но как достать оттуда заголовок поста, картинку и текст? Наконец, на сцену выходит BeautifulSoup. Сейчас вы получили HTML из response.text , но это просто строка с HTML кодом. Для работы с библиотекой BeautifulSoup нужно сделать из этой строки HTML-суп:
from bs4 import BeautifulSoup soup = BeautifulSoup(response.text, 'lxml') print(soup.prettify()) В Python-коде суп — это новый объект с кучей возможностей. Например, теперь можно вывести HTML красиво, с отступами, с помощью метода soup.prettify() :
DOCTYPE html> html lang="en-US"> head> meta charset="utf-8"/> meta content="width=device-width, initial-scale=1" name="viewport"/> title> Are You Grateful? . Супом он называется исторически, вот статья об этом термине. Если вкратце, то на самом деле верстальщики иногда косячат и, например, забывают закрывать теги или оставляют какие-нибудь неисправности. Такой код на HTML стали называть tag soup . Браузеры умеют самостоятельно исправлять какие-то огрехи и делать из такого “супа” нормальный, рабочий HTML. Но если вы скачиваете страничку через requests , то браузер тут ни при чём, и вы получите такой HTML, какой написали верстальщики сайта, со всеми его ошибками.
Для этого и нужна библиотека lxml , она подправит мелкие недочёты, и с ней BeautifulSoup справится даже с очень плохой вёрсткой. В этой строчке вы как раз говорите библиотеке BeautifulSoup использовать lxml :
soup = BeautifulSoup(response.text, 'lxml') Заголовок поста
Заголовок поста можно легко найти методом супа .find() . Для начала нужно узнать в какой тег этот заголовок обёрнут. В этом помогут инструменты разработчика:
Итак, тег h1 . Вот что вернёт метод .find() :
print(soup.find('h1')) #
Это тоже суп, но уже не со всей HTML-страницей, а только с этим тегом и тегами внутри него. Заголовка поста тут нет: пост называется Are You Grateful? , а такого текста в этом теге нет. Похоже, что это не тот тег , который вы искали. Их на странице несколько и BeautifulSoup4 выдал первый, который нашёл. Это тег , который находится в самом верху страницы:
Как же найти заголовок поста, а не страницы? Можно уточнить запрос: заголовок поста лежит в теге , а тот — в :
Давайте попробуем такой запрос:
title_tag = soup.find('main').find('header').find('h1') print(title_tag) # Are You Grateful?
Тег нашли, а как достать его текст? Всё очень просто:
title_tag = soup.find('main').find('header').find('h1') title_text = title_tag.text print(title_text) # Are You Grateful? Победа, вы добрались до заголовка поста!
Картинка поста
Картинку можно найти так же: это единственный тег внутри тега . Но давайте попробуем другой подход, найдём её по классу. У картинки есть классы:
У картинки есть 3 класса, они перечислены через пробел:
attachment-post-image size-post-image wp-post-image Класс attachment-post-image переводится как “Картинка поста”, а значит наверняка он есть только у картинок поста. Вот как найти тег img , у которого есть такой класс:
soup.find('img', class_='attachment-post-image') # ![]() # fortunate, things to be grateful for, why you should be grateful, Frank Sonnenberg" class token comment"># size-post-image wp-post-image" height="400" sizes="(max-width: 800px) 100vw, 800px" # src="https://www.franksonnenbergonline.com/wp-content/uploads/2019/10/image_are-you-grateful.jpg" ...
Тот же .find() , только указали параметр class_ . Нижнее подчёркивание разработчики библиотеки добавили для того, чтобы не было пересечения со словом class из Python, которое используется для создания классов.
Осталось достать адрес картинки, он лежит в аргументе src :
soup.find('img', class_='attachment-post-image')['src'] # https://www.franksonnenbergonline.com/wp-content/uploads/2019/10/image_are-you-grateful.jpg Домашнее задание
Осталось спарсить текст поста. Сделать это можно одним из способов выше: по классу или тегам, с помощью метода find .
Попробуйте бесплатные уроки по Python
Получите крутое код-ревью от практикующих программистов с разбором ошибок и рекомендациями, на что обратить внимание — бесплатно.
Переходите на страницу учебных модулей «Девмана» и выбирайте тему.